
Model Misspecifications in Metabolic Flux Analysis: Biases, Tests and Fixes
Rudiyanto Gunawan*,** , Sandro Hutter*,**
*Institute for Chemical and Bioengineering, ETH Zurich, Zurich, Switzerland
**Swiss Institute of Bioinformatics, Lausanne, Switzerland
Metabolic flux analysis (MFA) has become an indispensible tool in metabolic engineering, not only for analyzing metabolic phenotypes (flux distribution), but also for optimizing metabolic pathways to improve productivity and/or to gain new capabilities. The MFA is based on a stoichiometric model of the metabolic reaction network under the pseudo-steady state assumption. The simplest variant of the MFA, hereupon referred to as the overdetermined MFA, uses a reduced stoichiometric model of the cellÕs metabolism such that the flux estimation constitutes an over- (or fully) determined linear regression problem. Thanks to its simple formulation and numerical implementation, the overdetermined MFA is still widely used in metabolic engineering applications [1-2].
Despite the long history of MFA, the impact of misspecifications of the stoichiometric model, particularly the issue of missing or omitting reactions, has not received much attention. A recent study demonstrated that modeling errors could lead to gross uncertainty in the estimated intracellular flux values [3]. In this study, we employed the framework of linear least square regressions to quantify the effects of missing reactions on the flux estimates, and evaluated several statistical tests for detecting omitted reactions in the stoichiometric model. Finally, we proposed an iterative algorithm for resolving the issue of missing reactions in the overdetermined MFA.
The MFA can be formulated as a linear least square regression problem as follow:

where S denotes the stoichiometric matrix, v denotes the fluxes, the subscripts I and E refer to the intracellular and exchange (uptake) fluxes, respectively, and e denotes the vector of measurement errors. In the overdetermined MFA, the matrix SI has a full column rank and the exchange fluxes vE are measured (or could be computed from the measurements). Assuming that the error e has a zero mean and a constant variance, the ordinary least square (OLS) solution provide the minimum variance unbiased estimates (MVUE) for the intracellular fluxes vI as follow:
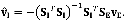
When the variance of the error is not constant but known, one can use the generalized least square estimation to provide the MVUE for vI. When the true model is in fact given by:
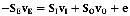
one can show that the OLS solution may no longer the MVUE because
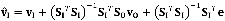
has a possible specification bias of

In the above derivation, the subscript O refers to the omitted reactions. Thus, the specification bias is non-zero when the omitted fluxes vO are non-zero and the missing reaction stoichiometry is not orthogonal to SI.
We demonstrated using a Chinese hamster ovary (CHO) metabolic model and cell culture data that the omission of even a single reaction from the network could lead to disproportionally large specification biases in the intracellular flux estimation. Importantly, while a poor statistical significance of the linear regression is a good indication of large specification biases, an acceptable statistical significance can still result from the omission of a reaction that causes significant flux biases.
We further evaluated three tests for detecting missing reactions, including RamseyÕs RESET test, F-test for model selection, and the Lagrange multiplier (LM) test [4]. Using 1000 randomly generated biochemical reaction networks [5] and in silico flux values, we computed the true positive, false positive, true negative and false negative rates of the above tests. The results showed that the F-test robustly outperforms the RESET and LM tests across different network sizes, numbers of omitted reactions, numbers of exchange fluxes and levels of errors.
Based on the above findings, we then proposed an iterative strategy to resolve the issue of missing reactions using the F-test. Briefly, in each iteration, we employed the F-test to detect whether the addition of a candidate reaction would lead to a statistically significant improvement in the linear regression. We then incorporated the reactions that passed the statistical threshold into the model, and repeated the F-tests for the remaining reactions against the updated model. Using the CHO metabolic model above and in silico generated data, we demonstrated that the proposed iterative strategy could recover the majority of missing reactions (~80%), and leave out reactions that were not part of the reaction network.
The findings of this study are available in a pre-print publication [6].
References:
1. Naderi, S.; Meshram, M.; Wei, C.; Mcconkey, B.; Ingalls, B.; Budman, H.; Scharer, J. Development of a mathematical model for evaluating the dynamics of normal and apoptotic Chinese hamster ovary cells. Biotechnol. Prog. 2011, 27, 1197–1205.
2. Nolan, R. P.; Lee, K. Dynamic model of CHO cell metabolism. Metab. Eng. 2011, 13, 108–24.
3. Sokolenko, S.; Quattrociocchi, M.; Aucoin, M. G. Identifying model error in metabolic flux analysis – a generalized least squares approach. BMC Syst. Biol. 2016, 10, 1–14.
4. Long, J. S.; Trivedi, P. K. Some Specification Tests for the Linear Regression Model. Sociol. Methods Res. 1992, 21, 161–204.
5. Aho, T.; Smolander, O.-P.; Niemi, J.; Yli-Harja, O. RMBNToolbox: random models for biochemical networks. BMC Syst. Biol. 2007, 1, 22.
6. R. Gunawan; S. Hutter. Assessing and Resolving Model Misspecifications in Metabolic Flux Analysis. Preprints. 2017, doi:10.20944/preprints201703.0124.v1.
See more of this Group/Topical: Computing and Systems Technology Division